SurgCast predicts future instrument skeletons from the current skeleton, robot state, and prospective actions, then uses these structures to control surgical video generation. Dual-Path Semantic-Kinematic Injection combines geometric residuals with global-local kinematic modulation, while distribution-matching distillation transfers this interface to a four-step causal student. Experiments on SutureBot and SRTH-Porcine-Cholei evaluate visual quality and instrument control, with additional zero-shot transfer and physical master-device demonstrations.
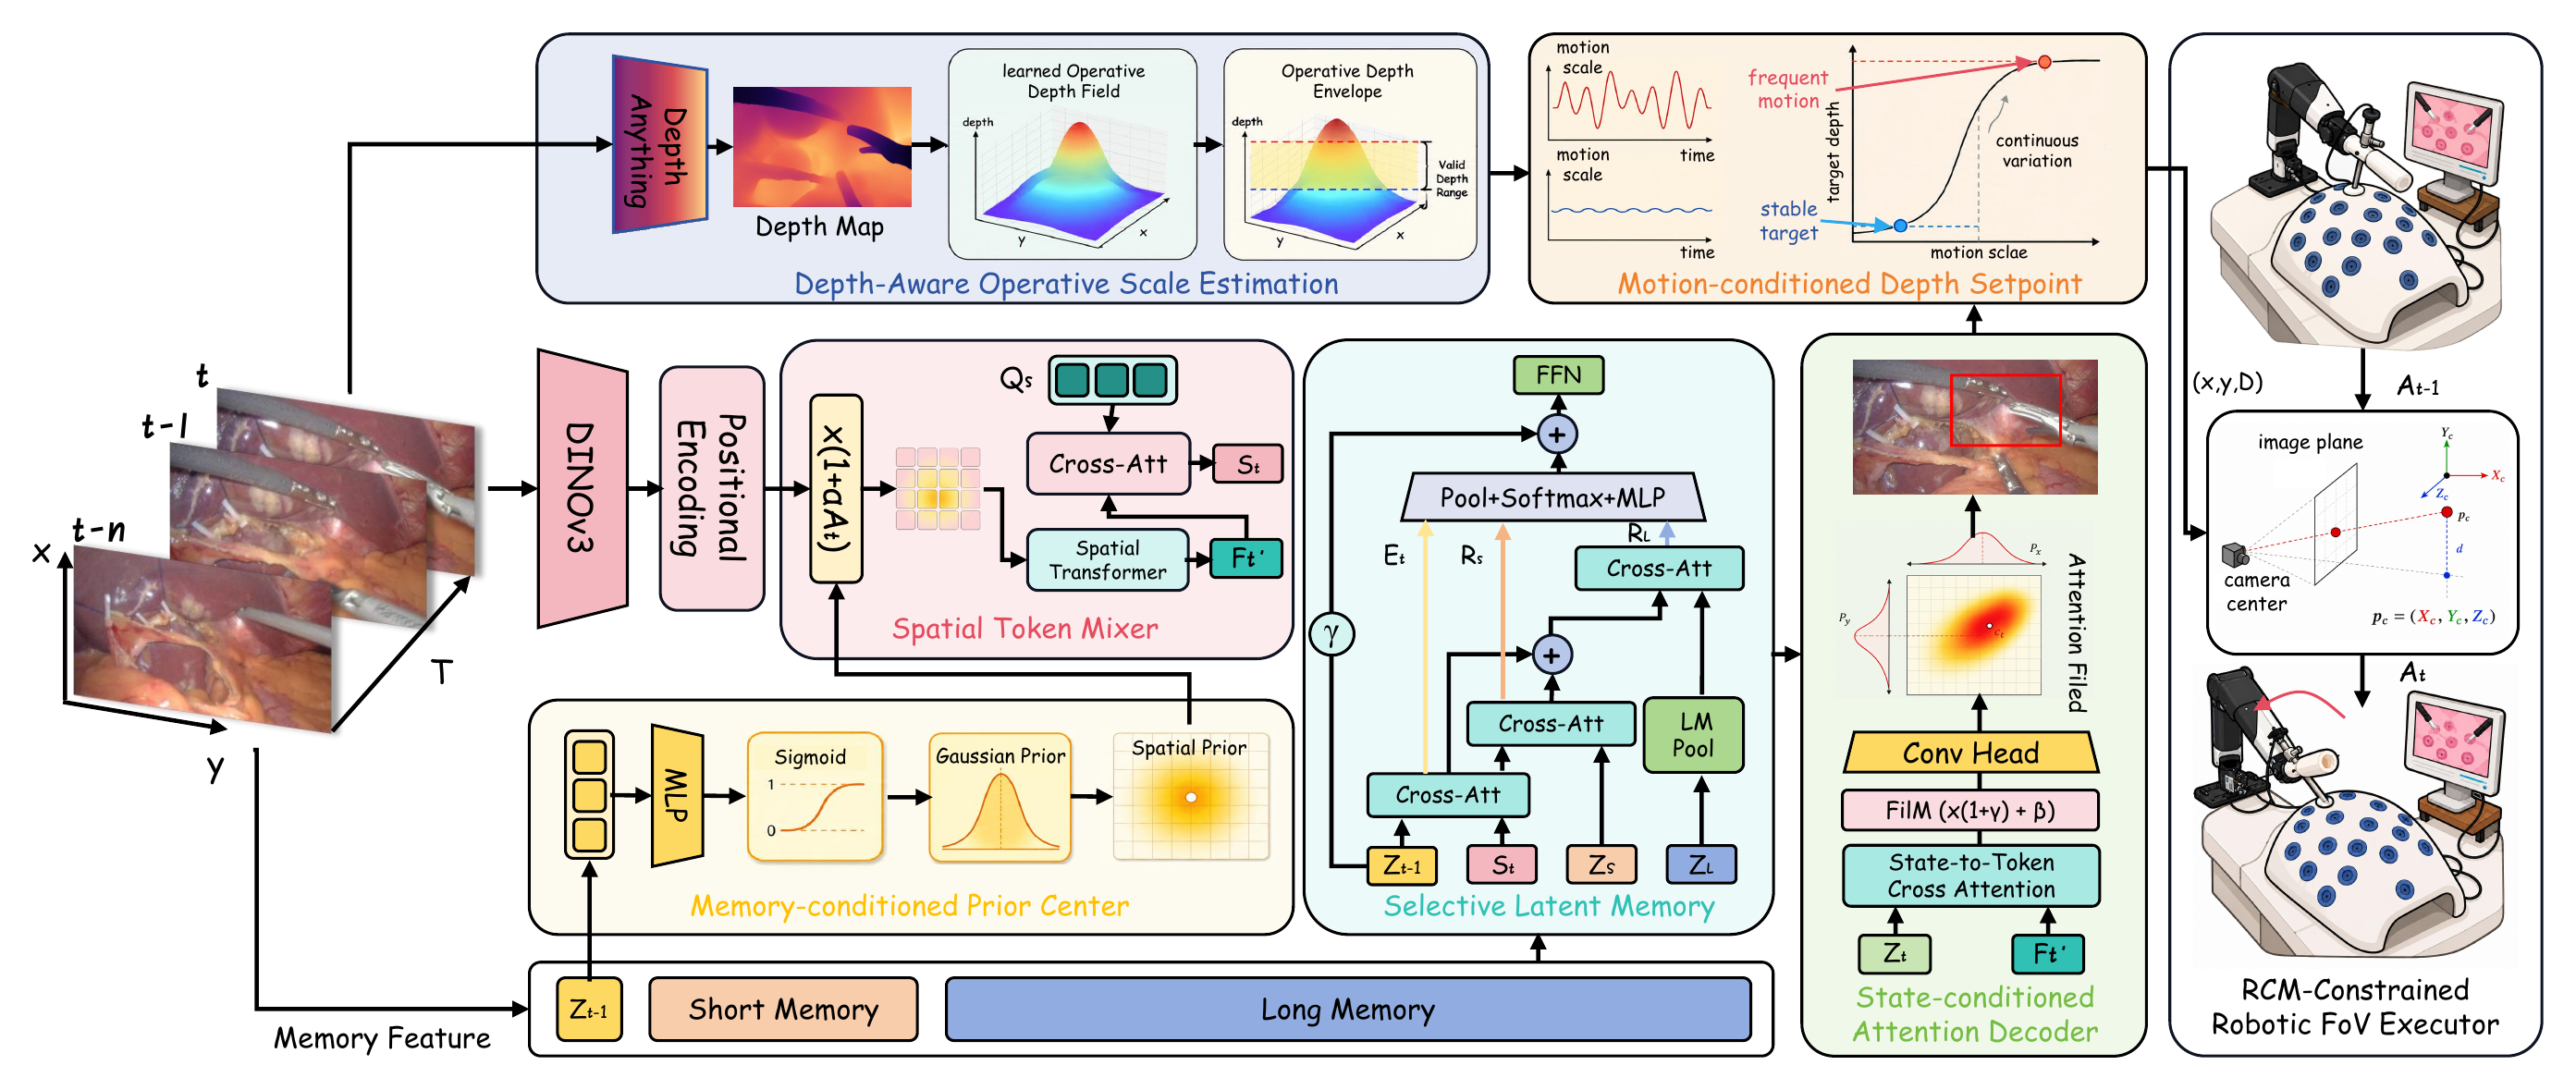
Autonomous laparoscopic camera control requires continuous understanding of the surgeon's operative intent in dynamic surgical scenes, where the target operative region is not a stable physical object but a latent and temporally evolving attention state. SurgLAT is a causal online framework that combines a frozen DINOv3 encoder, a state-conditioned spatial token mixer, and selective causal latent memory to decode probabilistic attention heatmaps and operative regions for downstream endoscope guidance. It further integrates depth-aware scale regulation with Remote Center of Motion constrained control and redundancy-aware null-space initialization. Experiments on real laparoscopic videos and a physical robotic laparoscope platform demonstrate robust online tracking and stable autonomous camera adjustment under occlusion, rapid motion, and target transitions.
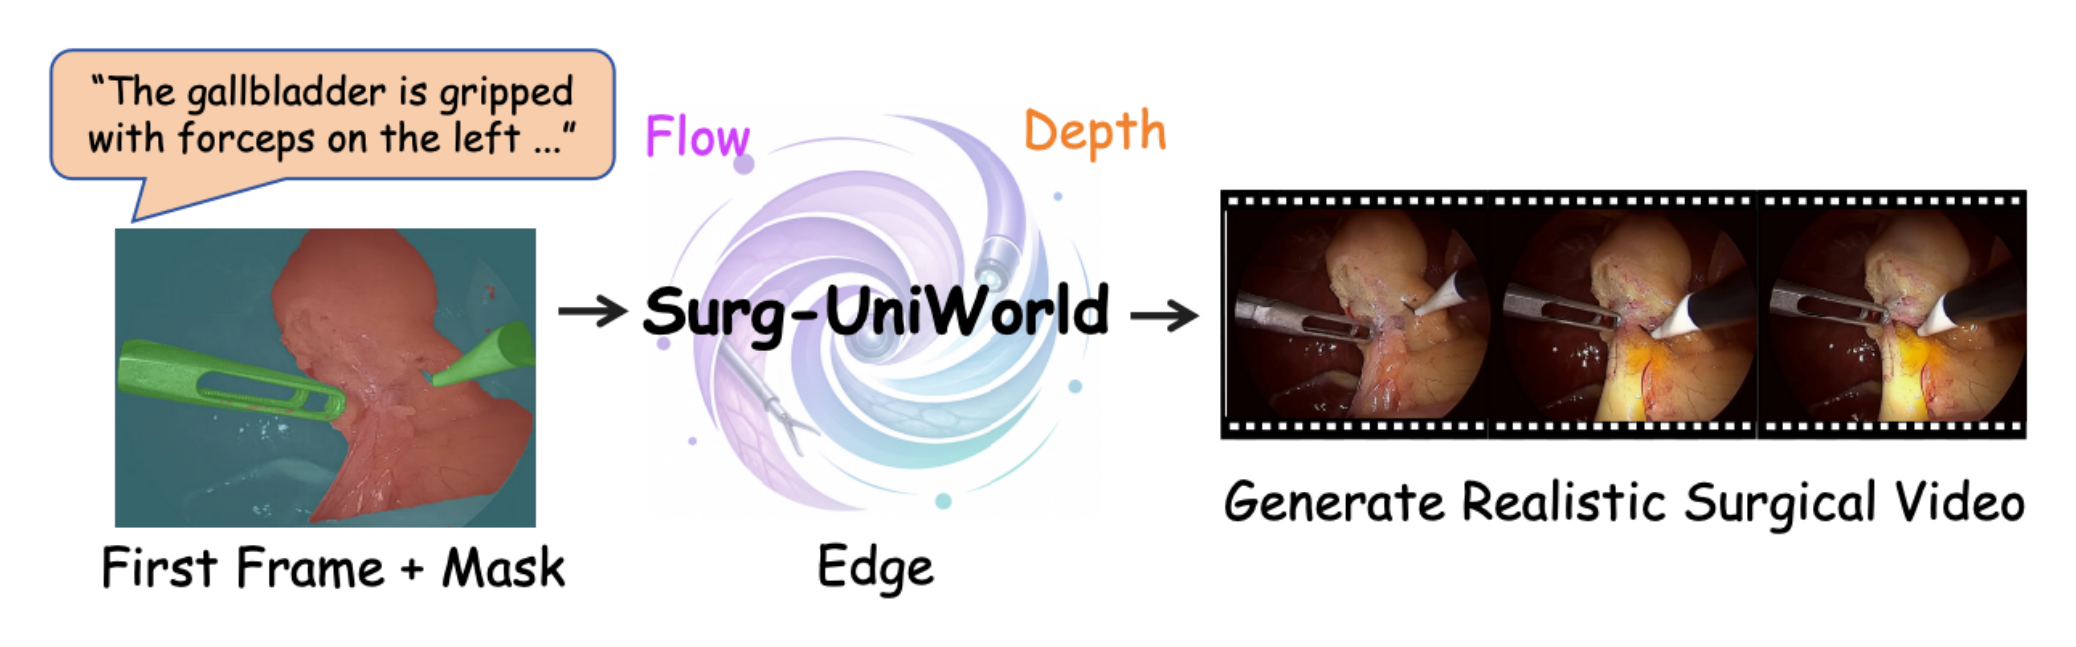
Controllable surgical world models can provide a generative foundation for surgical artificial intelligence and simulation by synthesizing realistic instrument-tissue interactions. Surg-UniWorld introduces a Hierarchical Surgical Anchor, Anchor-Relative Modality Experts, and a Multimodal Control Expert to support coherent video generation under arbitrary combinations of edge, depth, and optical-flow controls. Experiments demonstrate improved generation quality, temporal consistency, and multimodal controllability.
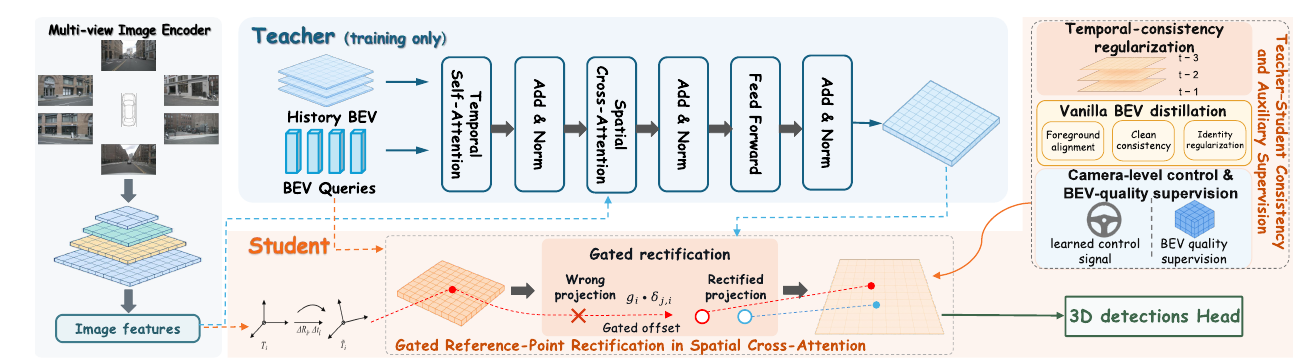
Camera-based bird's-eye-view 3D detection typically assumes accurate and fixed camera extrinsics. NCGR compensates for projection errors with a gated query-camera-specific rectification offset inside spatial cross-attention, while transitioning from perturbation-derived controls during training to a learned camera-level signal for blind inference. Experiments on nuScenes show substantially improved robustness under dynamic and static extrinsic perturbations.
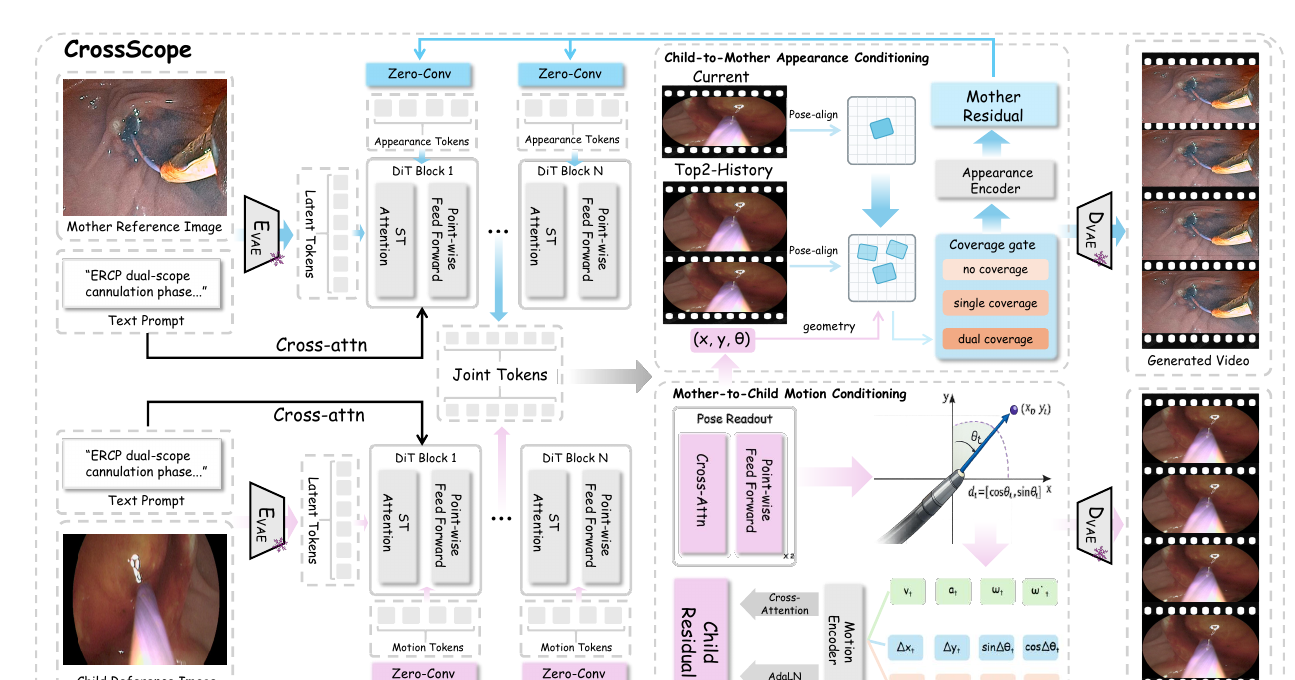
CrossScope studies role-asymmetric future prediction for Mother-Child endoscopic retrograde cholangiopancreatography, where two independently moving scopes provide complementary views without calibrated stereo geometry. Its dual-stream world model preserves view-specific experts and routes cross-view evidence according to target-specific spatial requirements, improving visual fidelity, structural preservation, target localization, and motion consistency.
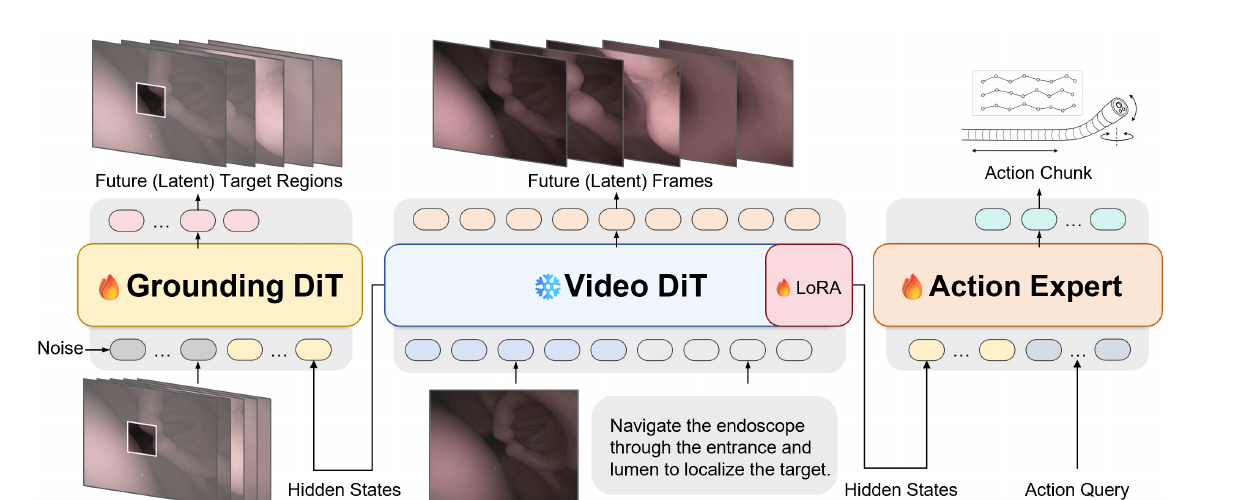
EndoWAM is a grounded World-Action Model for generalizable robotic endoscopic navigation. It predicts task-relevant target regions in future observations and couples a lightweight diffusion transformer with a discrete action expert through a shared predictive representation. The model enables real-time control and generalizes to unseen viewpoints, environments, and targets across multiple endoscopic procedures.
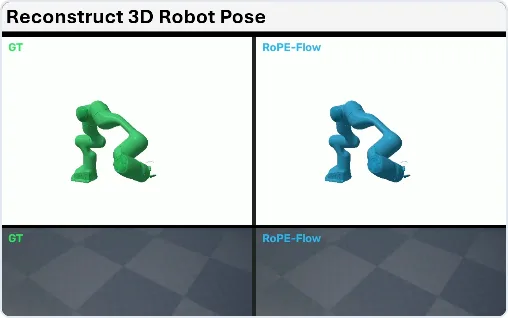
RoPE-Flow estimates robot 3D keypoints and joint angles from monocular images using graph-conditioned flow matching. A keypoint feature extractor combines positional cues with multi-scale appearance features, and graph-guided condition generation models correlations among keypoints. Bone-length and ray-depth losses promote topological consistency and scale stability. Evaluation covers different robot types and cameras, including a cross-scene benchmark for zero-shot robot pose estimation.
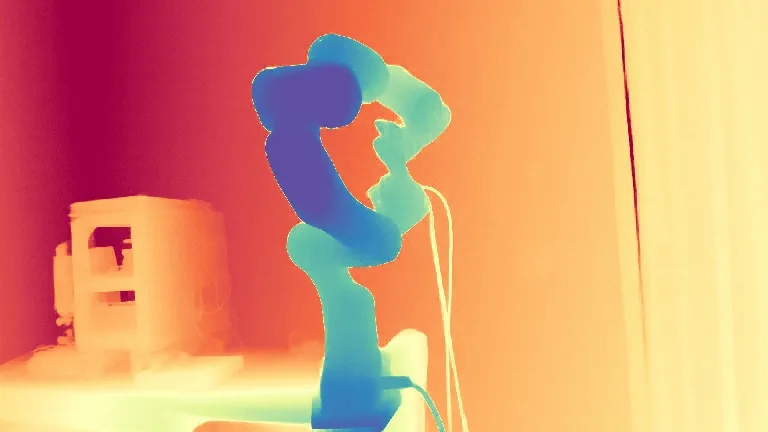
FlowMoDE is a coarse-to-fine flow-matching framework for efficient, structure-aware monocular depth estimation with sim-to-real and cross-scene generalization. It conditions coarse depth decoding on diffused features from a pre-trained semantic encoder, then restores fine structural details through expanded decoding layers. Trained on a single synthetic indoor dataset, it is evaluated on five real-world indoor and outdoor datasets for depth estimation and point-cloud reconstruction, with additional qualitative comparisons in robotic scenes.
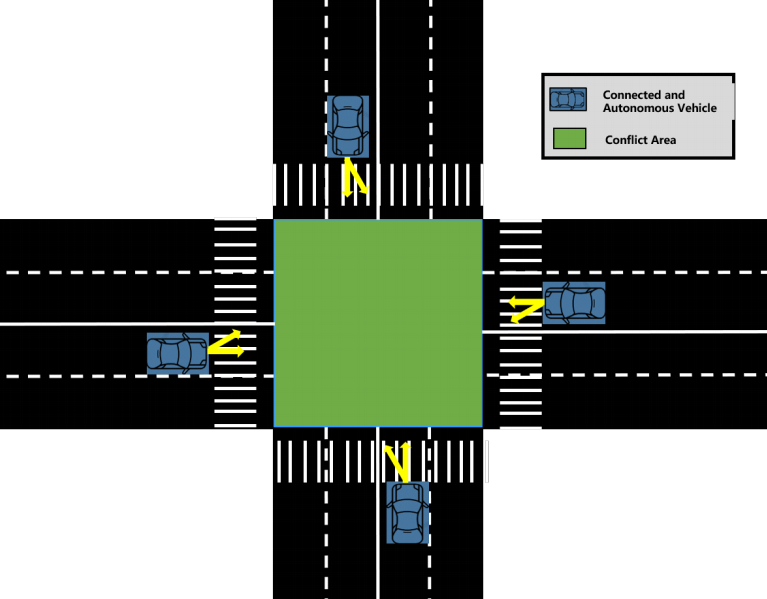
This work formulates multi-vehicle coordination at unsignalized intersections as a Markov decision process and introduces a collision-risk function with conflict-prioritized experience replay for Soft Actor-Critic. Simulations under ROS demonstrate improved coordination efficiency and safety.
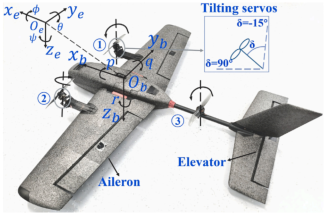
This paper proposes an observer-based prescribed-time adaptive control strategy for tiltrotor UAV attitude control under mismatched disturbances, actuator faults, and input saturation. Hardware-in-the-loop experiments validate prescribed-time convergence, robustness, and fault tolerance.
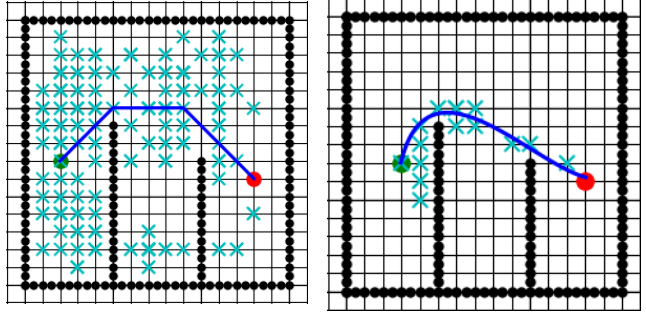
This paper improves the Jump Point Search algorithm for intelligent warehouse robot path planning with a heuristic function that considers both distance to the goal and path cost. Experiments on a real warehouse robot demonstrate improved path-planning performance.